Parallelism (ML Training)
See this for the different paradigms: https://colossalai.org/docs/concepts/paradigms_of_parallelism/
Read this guide here, and watch the CS336 videos
- Ultrascale playbook by HuggingFace
A Transformer operates on tensors of shape . The four parallelism dimensions split different axes:
| Scheme | Axis |
|---|---|
| Data Parallelism | Batch |
| Sequence Parallelism and Context Parallelism | Sequence |
| Pipeline Parallelism | Layer |
| Tensor Parallelism | Dim |
Resources
- https://docs.nvidia.com/megatron-core/developer-guide/latest/user-guide/features/moe.html
- https://docs.nvidia.com/nemo/megatron-bridge/latest/parallelisms.html
- https://main-horse.github.io/posts/visualizing-6d/#pipelining-and-fsdp
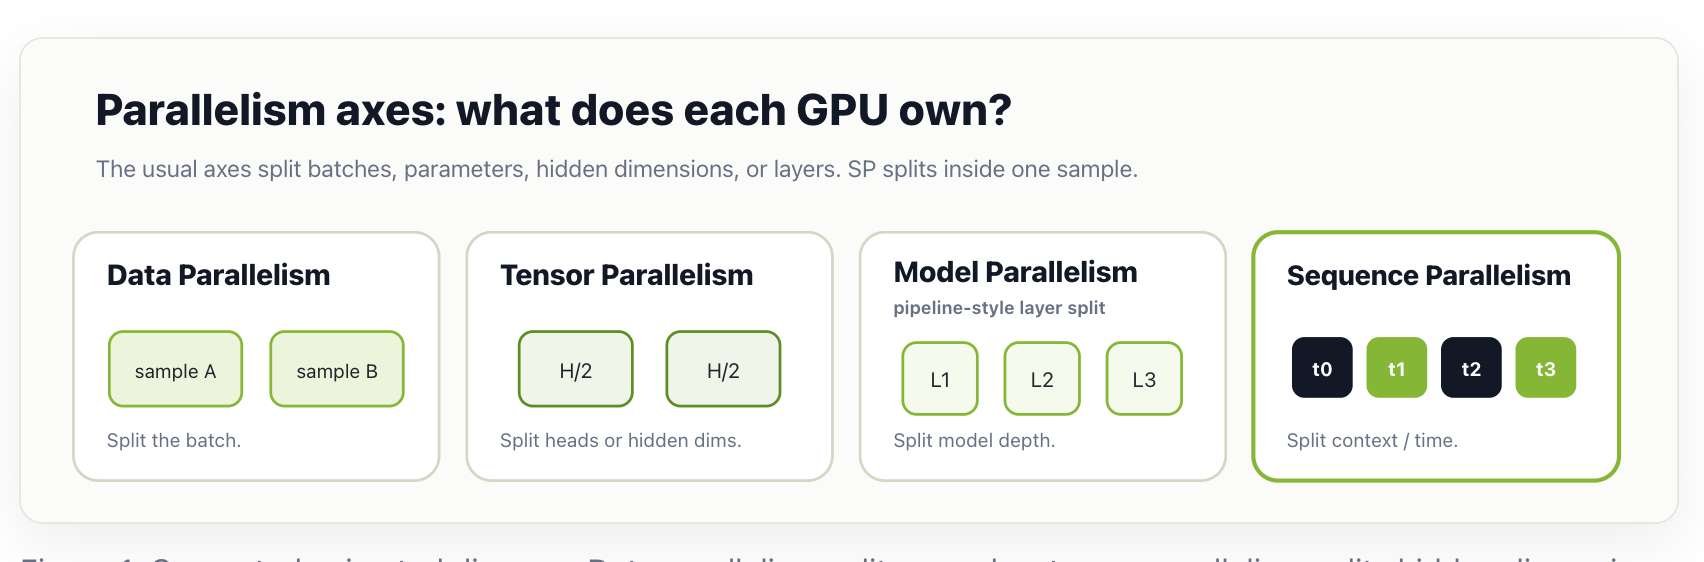
Forms of parallelism:
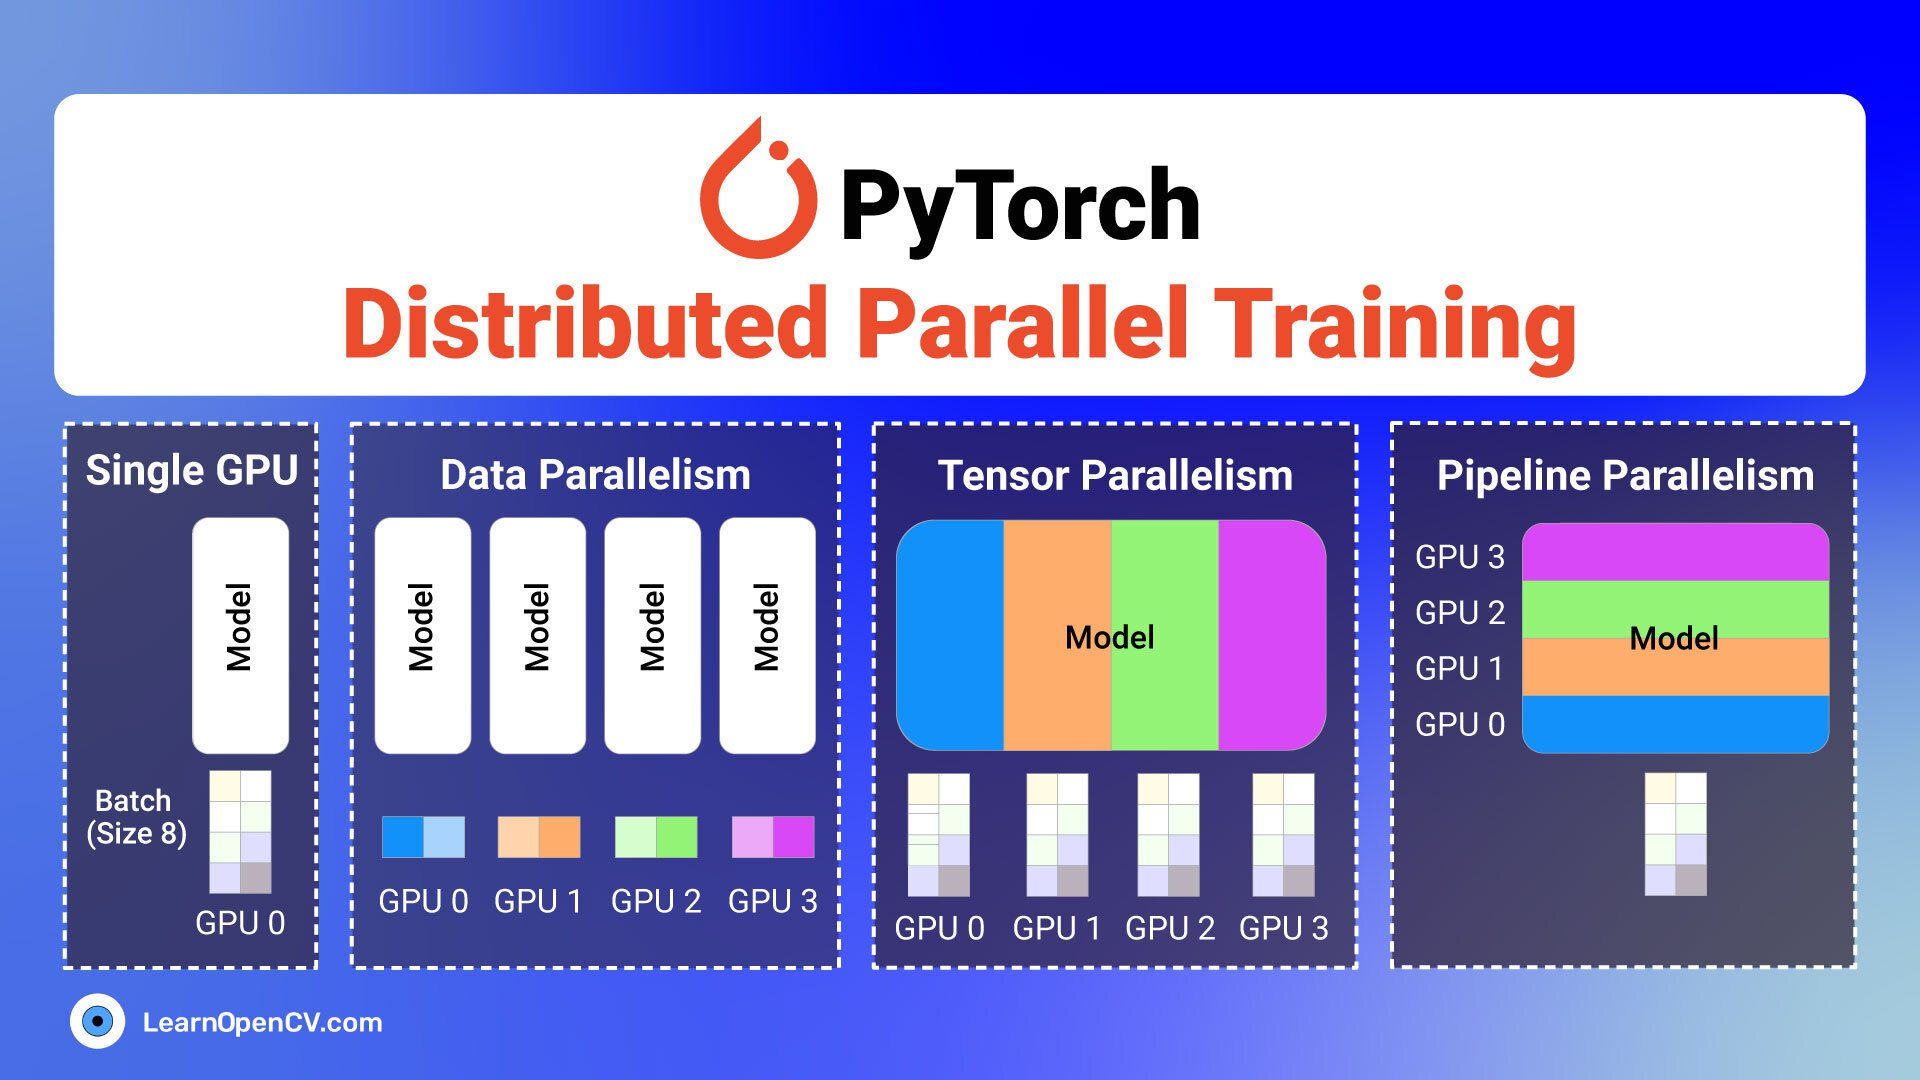
These seem like a great set of walkthroughs: https://uvadlc-notebooks.readthedocs.io/en/latest/tutorial_notebooks/scaling/JAX/single_gpu_techniques.html
Resources
- Data-Parallel Distributed Training of Deep Learning Models
- Pipeline-Parallelism: Distributed Training via Model Partitioning
Really good blog from JAX
- https://jax-ml.github.io/scaling-book/training/#tensor-parallelism
- First cited by this https://fleetwood.dev/posts/domain-specific-architectures, which I mention in AI Inference
There are 2 ways to parallelize: https://docs.oneflow.org/en/v0.4.0/extended_topics/model_mixed_parallel.html