Do generative video models understand physical principles?
I remember seeing someone read this on tweeter, and this was the first paper on world models that I skimmed through.
But essentially as of Feb 2025, they don’t. It’s a really good benchmark.
“Proponents argue that the way the models are trained— predicting how videos continue, a.k.a. next frame prediction— is a task that forces models to understand physical principles”
- Now, we can actually prove this by running a benchmark
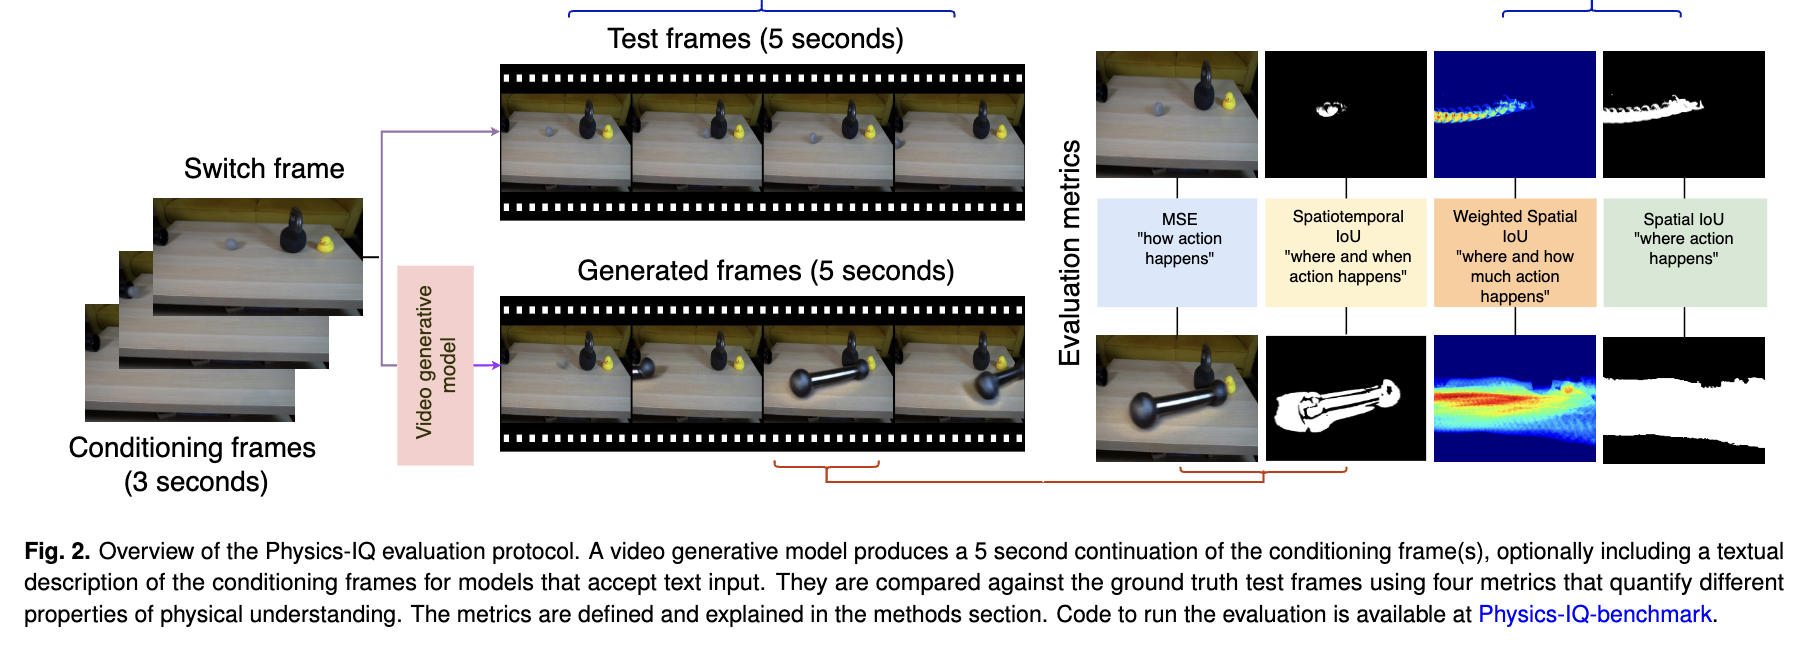
These are the metrics that they use:
- Where does action happen? Spatial IoU
- Where & when does action happen? Spatiotemporal IoU
- Where & how much action happens? Weighted spatial IoU
- How does action happen? MSE
How are the masks generated?
Just some classical computer vision techniques (see algorithm 2).
Citation
(Motamed et al., 2025)
Motamed, S., Culp, L., Swersky, K., Jaini, P., & Geirhos, R. (2025). Do generative video models understand physical principles? https://arxiv.org/pdf/2501.09038