Image as a Foreign Language: BEiT Pretraining for All Vision and Vision-Language Tasks
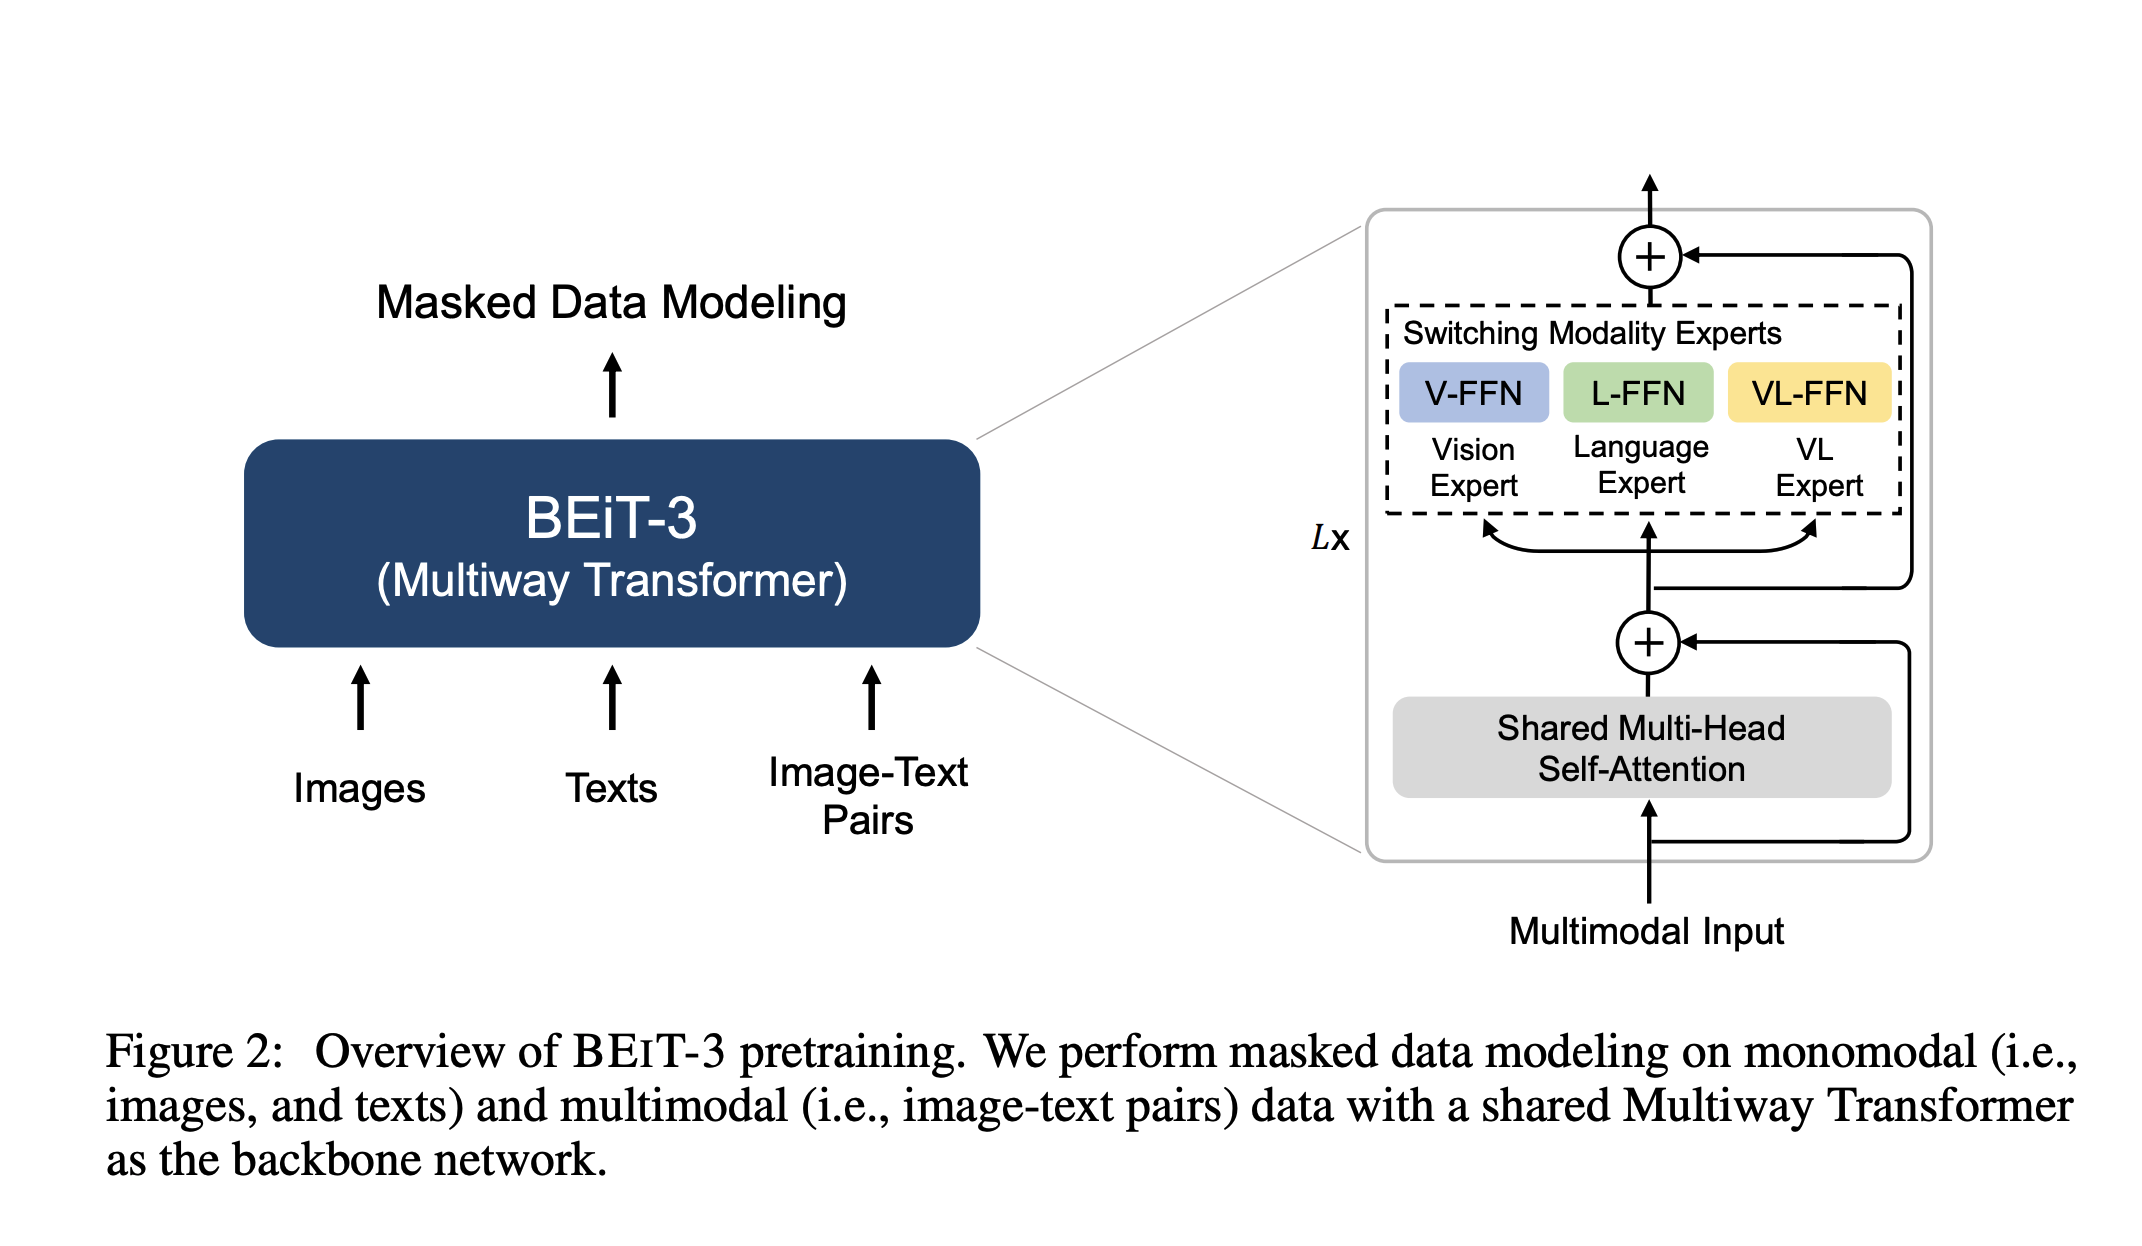
BEIT-3 is a general-purpose multimodal foundation model.
Paper:
Citation
(Wang et al., 2022)
Wang, W., Bao, H., Dong, L., Bjorck, J., Peng, Z., Liu, Q., Aggarwal, K., Mohammed, O. K., Singhal, S., Som, S., & Wei, F. (2022). Image as a Foreign Language: BEiT Pretraining for All Vision and Vision-Language Tasks. https://arxiv.org/pdf/2208.10442