Flow Q-Learning
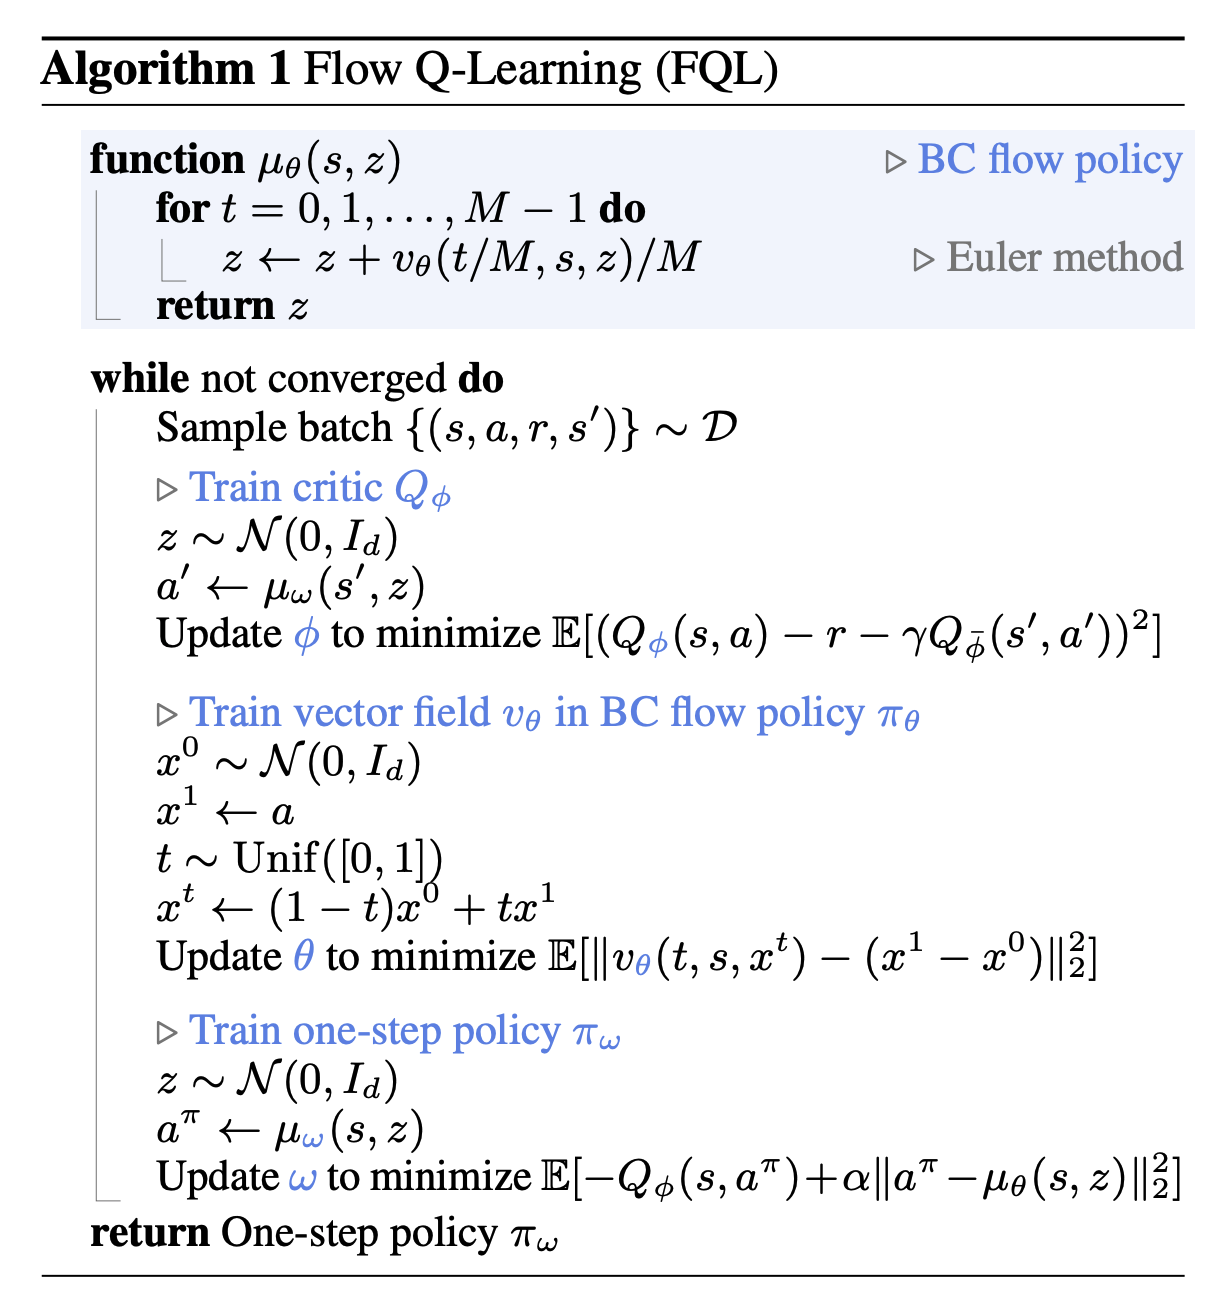
Their intuition is to train a 1-step policy as opposed to the BC flow policy.
“However, leveraging flow or diffusion models to parameterize policies for offline RL is not a trivial problem. Unlike with simpler policy classes, such as Gaussian policies, there is no straightforward way to train the flow or diffusion policies to maximize a learned value function, due to the iterative nature of these generative models. This is an example of a policy extraction problem, which is known to be a key challenge in offline RL in general”
Citation
(Park et al., 2025)
Park, S., Li, Q., & Levine, S. (2025). Flow Q-Learning. https://arxiv.org/abs/2502.02538