What Matters for Batch Online Reinforcement Learning
Diversity
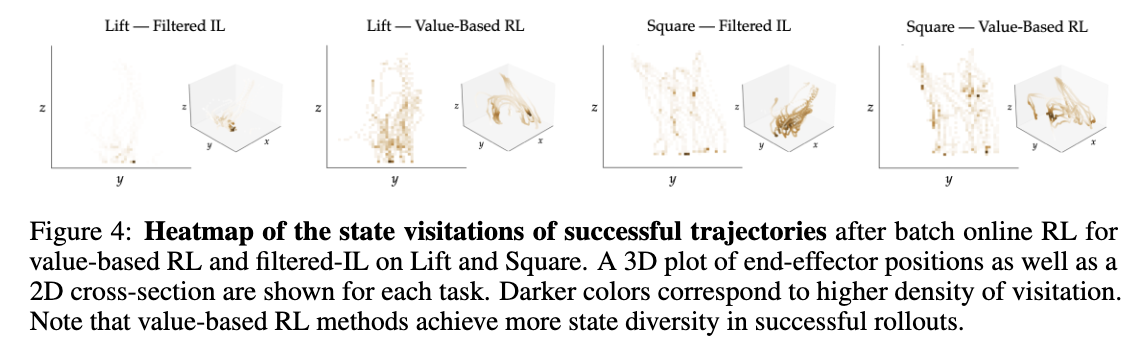
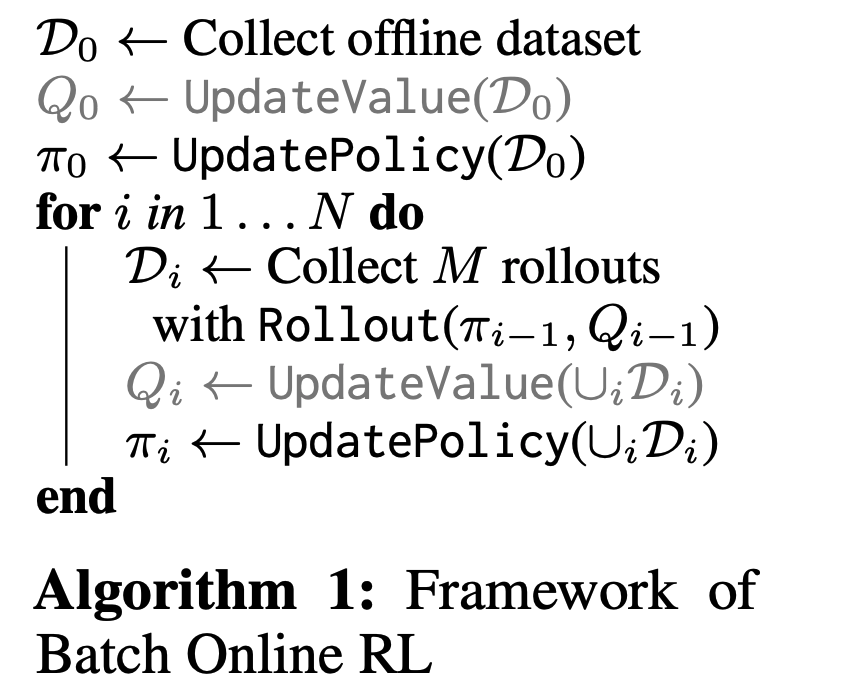
RL is from the Q function
- And they use IQL
One really important thing that they show is that implicit policy extraction is a lot better than explicit.
- Explicit is training the policy using the q-function
- Implicit policy extraction is doing multi-trajectory sampling, scoring trajectories, and selecting it
Citation
(Dong et al., 2025)
Dong, P., Mirchandani, S., Sadigh, D., & Finn, C. (2025). What Matters for Batch Online Reinforcement Learning in Robotics? https://arxiv.org/abs/2505.08078