Bootstrap your own latent: A new approach to self-supervised Learning (BYOL)
Seems like quite an important paper that V-JEPA mentions for preventing mode collapse.
where:
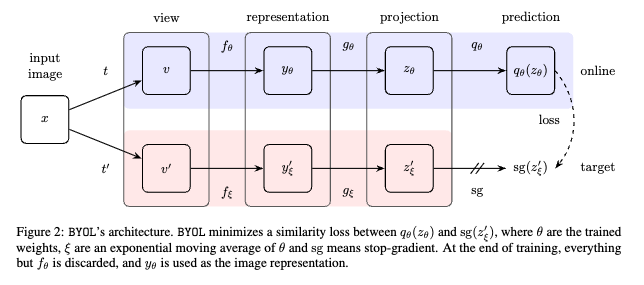
- , are representations from the online encoder given two augmentations of the same image,
- , are representations from the target encoder (parameters updated via EMA),
- is the predictor head on the online branch,
- means stop-gradient (no gradients flow into the target encoder),
- is the squared distance (MSE).
Intuition
Each online view predicts the target’s representation of the other view. No negatives are involved, collapse is prevented by stop-grad + predictor + momentum target.
Related
Citation
(Grill et al., 2020)
Grill, J.-B., Strub, F., Altché, F., Tallec, C., Richemond, P. H., Buchatskaya, E., Doersch, C., Pires, B. A., Guo, Z. D., Azar, M. G., Piot, B., Kavukcuoglu, K., Munos, R., & Valko, M. (2020). Bootstrap your own latent: A new approach to self-supervised Learning (BYOL). https://arxiv.org/pdf/2006.07733